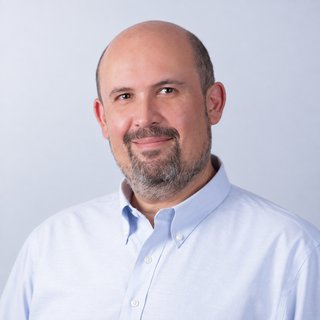
Dr. Sami Kama
Founder & CEO- 17 years at CERN
- Inventor, TensorFlow-TensorRT Integration (NVIDIA)
- Inventor and Architect, AWS SageMaker
- Inventor and Architect, AWS SageMaker HyperPod
- Creator, SageMaker Profiler (world’s first distributed AI profiler)

training · inference · agents
You keep control of your infrastructure, policies, and data.
Nucleaton™ manages your GPU cluster operations and schedules compute for training, inference and agents.
Run multi-node training and production inference on the same cluster.
Automatically isolate faulty nodes using the most advanced real-time telemetry. Reduce job failures and wasted compute hours.
Reallocate compute between training and inference to reduce GPU idle time.
“C-Gen.AI dynamically allocates idle compute to inference workloads, so AI resources are continuously utilized rather than sitting idle.”
 Dr. Sami KamaFounder & CEO, C-Gen.AI
The cost of idle GPUs
<50%
GPU capacity is used on many AI clusters between training runs.
You still pay for the idle capacity.
GPU utilization over 24 hours, from 03:00. Before Nucleaton™: before working hours (03:00 to 09:00) inference uses 40% of the cluster and 60% of GPUs sit idle; in working hours (09:00 to 13:00) inference rises to 80% and 20% still sit idle. With Nucleaton™: for the rest of working hours (13:00 to 18:00) inference takes 80% and training the idle 20%; after hours (18:00 to 03:00) inference eases back to 40% and training takes the other 60%. With Nucleaton™ the cluster stays close to 100% busy.
Save seed capital on infrastructure engineering. Launch AI models faster.
Turn idle cluster compute into revenue with multi-tenant AI-as-a-Service.
Run secure, on-premises AI with built-in audit logs and cost attribution.
We’ve designed, built and run some of the largest AI training and inference systems in production.
Can’t find your answer? Contact us.
Stop managing infrastructure and start scaling.
Sit back and watch our products in action.
No commitment required.
Kimi K3 and GLM 5.3 on one B300 node: speed vs API providers, and the monthly volume where owning beats paying per token.
How unified AI orchestration enables headcount independence and optimized GPU utilization for production-grade workloads.
AI holds enormous promise — from powering customer insights to enabling predictive maintenance. But complexity has a price.