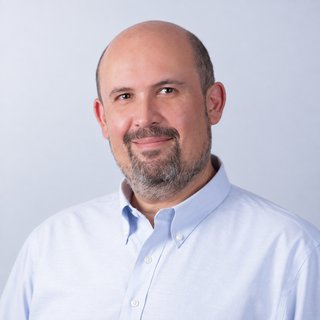
Dr. Sami Kama
Founder & CEO- 17 years at CERN
- Inventor, TensorFlow-TensorRT Integration (NVIDIA)
- Inventor and Architect, AWS SageMaker
- Inventor and Architect, AWS SageMaker HyperPod
- Creator, SageMaker Profiler (world’s first distributed AI profiler)

Run training, production inference, and agents on infrastructure you control. Nucleaton™ brings compute, workloads, and production data under one resource and governance model, so capacity can move where it is needed and selected data created in production can remain available for evaluation and future training.
Train. Deploy. Learn from production. Train again.
Talk to an engineerTraining
Jobsqueuescheckpoints
compute + storageDeploy
Inference
Endpointstrafficagents
live servingLearn
Data + Improvement
Tracesfeedbackevaluation
under your governanceTrain again
One Nucleaton™-controlled environment.
One resource policy • one data boundary • one operating model. Workloads remain distinct; infrastructure and governance share one foundation.
One AI Lifecycle
Training, inference, and agents are often deployed as separate systems, each with its own compute, headroom, operations, and data path. Nucleaton™ brings those workloads under one resource and governance model.
Three separate systems
Training
Inference + Agents
Data + Improvement
Capacity is fixed per system, and each one also carries its own operations and data path.
Pooled with Nucleaton™
One Nucleaton™ Environment
Training
Inference + Agents
Data + Improvement
All three share compute, storage and headroom under one policy, one operating model and one data boundary.
One environment. One resource policy. One data boundary.
Capacity Economics
Peak training, production inference, and agent workloads each need room to grow. When they live in separate resource pools, each pool carries its own unused headroom. Nucleaton™ lets eligible capacity move between workloads according to the priorities you define.
Use already-committed compute before buying more compute elsewhere.
This is not free compute. Power, storage, networking, and operations still have cost. The advantage is reducing unnecessary duplication of committed capacity.
Separate pools
Each pool is sized for its own peak. Three sets of unused headroom: 97 GPUs held in reserve.
Prioritized shared pool
Same Work, One Pool, One Headroom
Illustrative figures. Actual headroom depends on workload timing and your priorities.
Peaks rarely coincide, so one shared headroom covers them all: 35 GPUs held in reserve, and 62 fewer GPUs to buy.
Reuse headroom instead of duplicating it.
Customer-Defined Policy
You decide what must remain available, what can be used opportunistically, and how resources return when higher-priority work arrives. Nucleaton™ enforces those decisions continuously.
One example of how a policy plays out
This is one example. How much is protected, which workloads come first and how capacity is reclaimed are all set by your policy.
Guaranteed 18Held 12Training 30Inference 30Agents 10
Guaranteed 18Held 12Training 30Draining 20Inf. 10Agents 10
Guaranteed 18Held 12Training 50Inf. 10Agents 10
Your team defines the architecture and policies.
Nucleaton™ automates their execution.
Privacy + Sovereignty + Data
Agent traces, model responses, corrections, evaluations, and workflow outcomes can become valuable inputs to future evaluation and model improvement.
Running the serving system inside infrastructure you control keeps selected production data within your AI environment and under your governance.
Customer-controlled boundary
Models + Agents
InferencetoolsRAG
Production Data
Tracesfeedbackoutcomes
Storage + Keys
Customer controlled
Models, production data, storage and keys stay inside infrastructure you control.
Governed improvement path
You decide what is kept and what is used for training.
Your production data stays yours, and keeps improving your models.
Compound the Intelligence
Make clusters support the full AI lifecycle.
Training, inference, agents, users, storage, health, and resource policies under one infrastructure foundation.
Turn physical GPU capacity into an operated AI service. Connect tenant/service contracts to the physical fleet, improve eligible capacity utilization, and offer managed training, inference, and agent services.
For data center operatorsResource Authority
AI training needs deterministic access to scarce accelerators, multi-node coordination, queues, priorities, and accounting. Nucleaton™ uses Slurm as the base resource authority so training, inference, agents, and CPU workloads draw from one resource model.
Starting fresh? Nucleaton™ can build the environment.
Already have Slurm? Existing clusters can be integrated through an assisted brownfield deployment.
Inference scalingRouting + endpointsPriority + reclaimUsers + storageHealth + remediation
For workloads that need Kubernetes semantics, on the same physical fleet.
inference endpointsagent hostingmodel serving
CPU/GPU allocationmulti-node jobsqueuesprioritiesaccounting
Platform Depth
Workloads
TrainingInferenceAgentsEvaluationCPU/Data services
Operations
AutoscaleRoutePrioritizeReclaim/DrainHealth/Remediate
Control
UsersProjectsQuotasAccessPolicy
Cluster
SlurmStorageNetworkGPU stackOptional K8s
Infrastructure
NVIDIAAMDCPUCloudData Center
Engineering Depth
Deployment time subject to infrastructure availability. Initial model download and container conversion are separate, model-dependent preparation steps.
Nucleaton™ automates work an infrastructure team would otherwise build and operate: cluster lifecycle, workload control, routing, scaling, monitoring, and resource enforcement. Your team still owns the architecture, priorities, access model, workload policies, and operational boundaries.
The goal is to stop making the infrastructure team rebuild the same control-plane machinery.
Can’t find your answer? Contact us.
Sit back and watch our products in action.
No commitment required.
At C-Gen.AI, we see ourselves as the connective tissue between model innovation and operational delivery for startups, data centers, and enterprises.
More about us