Skip to content

A production Slurm GPU cluster, deployed in about 25 minutes.

Nucleaton™ deploys and runs Slurm on your GPUs, on popular clouds or your own servers, and adds what a production cluster needs: inference endpoints, real-time observability, usage reports, projects with quotas and automatic GPU fault handling.

What gets deployedArchitecture
  1. Your workloadsTraining jobs · inference endpoints
  2. Nucleaton™ servicesObservability · usage reports · projects and quotas · GPU fault handling · endpoints
  3. Optional Kubernetes overlayFor teams that deploy with containers
  4. SlurmResource authority: queues, priorities, partitions, accounting
  5. Your GPUsOn Nebius, Google Cloud, Azure, DigitalOcean, OCI, AWS or your own servers

Everything a working Slurm GPU cluster needs.

Nucleaton™ doesn’t replace Slurm. It extends it, so your team keeps the scheduler it knows and gets the rest of the platform around it.
  • Deployed for you

    A new cluster is deployed and configured automatically, with no hand-written setup scripts.

  • Slurm, ready for GPU training

    Queues, priorities, partitions, fair scheduling and accounting across multi-node GPU jobs.

  • Inference on the same cluster

    Endpoints with request routing and demand-driven scaling, running alongside training on the same GPU pool.

  • Observability included

    Real-time telemetry for every GPU, job and endpoint, without assembling your own monitoring stack.

  • Projects, users, quotas

    Organize teams into projects with their own users, storage and GPU quotas.

  • GPU fault handling

    Failing GPU nodes are detected from telemetry, isolated and replaced automatically.

One Slurm platform on every cloud you use.

Each cloud has its own way to stand up Slurm, such as AWS ParallelCluster and AWS PCS, Google Cloud Cluster Toolkit, Azure CycleCloud or Nebius Soperator. Nucleaton™ gives you one platform that works the same way across popular clouds and your own hardware, with inference, observability and usage reporting built in.

  • NebiusGPU VMs in your Nebius AI Cloud account
  • Google CloudCompute Engine GPU VMs in your project
  • Microsoft AzureND-series GPU VMs in your subscription
  • DigitalOceanGPU Droplets in your account
  • Oracle Cloud (OCI)Bare metal GPU instances in your tenancy
  • AWSEC2 GPU instances in your account
  • Your own serversBare metal GPU servers in your data center

Bring your existing cluster with you.

Existing Slurm clusters join Nucleaton™ through an assisted deployment. Slurm stays the scheduler your engineers know, and the cluster gains inference endpoints, observability, usage reports and automatic GPU fault handling.

Assisted onboardingIllustrative
  • Existing Slurm clusterConnected
  • SlurmStill the scheduler
  • ObservabilityAdded
  • Usage reportsAdded
  • Inference endpointsAdded

What Slurm does, and what a GPU cluster needs around it

A short primer for teams deciding how to run their first, or next, GPU cluster.

By the C-Gen.AI engineering team

What Slurm is

Slurm is an open-source workload manager for Linux clusters. It decides which job runs on which nodes and when, keeps the rest waiting in a queue and can record what every job used. Nodes are grouped into partitions that work as job queues, and plugins add accounting, limits per user or account and multifactor job priorities.

Why AI teams choose it

Distributed training needs many GPUs allocated at the same moment, on nodes that can exchange data quickly. Slurm comes from high-performance computing, where large parallel jobs like this are routine, so multi-node allocation, queues and priorities work without extra tooling. Many researchers already know it from university and national lab clusters.

What Slurm leaves to you

Slurm schedules work. It doesn’t provision cloud GPUs, install drivers, watch GPU health, serve models to users or turn accounting records into reports a finance team can read. Teams usually build those pieces themselves, around the scheduler, and then keep maintaining them.

Questions to ask before you build

How long until the first job runs? Who maintains monitoring when the person who set it up moves on? What happens when a GPU fails halfway through a multi-day run? Where will the model you just trained be served? The answers decide whether the cluster becomes a project or a platform.
Led by a world-class team

We’ve designed, built and run some of the largest AI training and inference systems in production.

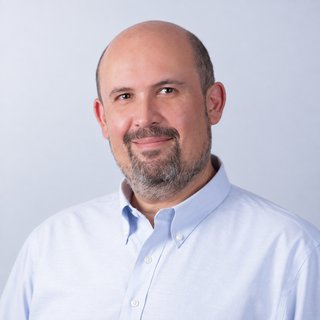
Dr. Sami Kama

Dr. Sami Kama

Founder & CEO
  • 17 years at CERN
  • Inventor, TensorFlow-TensorRT Integration (NVIDIA)
  • Inventor and Architect, AWS SageMaker
  • Inventor and Architect, AWS SageMaker HyperPod
  • Creator, SageMaker Profiler (world’s first distributed AI profiler)
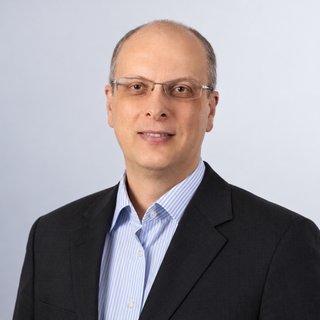
Richard Vencu

Richard Vencu

Head of Engineering
  • Former Head of HPC & MLOps, Stability AI
  • Managed one of the world’s largest AI training clusters
  • Co-Founder & Engineering Lead, LAION

Slurm on Nucleaton™

Is this real Slurm?
Yes. Slurm is the resource authority at the base of every Nucleaton™ cluster. Nucleaton™ services run on top of it.
Do we need Kubernetes?
No. Kubernetes is an optional overlay on top of Slurm, for teams that want to deploy with containers.
Which clouds are supported?
Nebius, Google Cloud, Microsoft Azure, DigitalOcean, Oracle Cloud Infrastructure and AWS, plus your own GPU servers.
How long does deployment take?
A typical greenfield cluster deploys in about 25 minutes. Existing clusters are brought in with an assisted deployment.

Plan your Slurm GPU cluster

Tell us where your GPUs are and what you want to run. We’ll show you the cluster Nucleaton™ would deploy.

AWS ParallelCluster, AWS PCS, Google Cloud Cluster Toolkit, Azure CycleCloud and Nebius Soperator are products of their respective owners. C-Gen.AI is an official Oracle partner and is not affiliated with Amazon Web Services, Google, Microsoft, DigitalOcean or Nebius.

Our engineers usually reply within 4 business hours. See our Privacy Policy.