Skip to content

You’ve committed to the GPUs. Put every hour to work.

Reserved GPU capacity is billed whether it’s busy or not. Nucleaton™ runs training and inference at the same time on the GPUs you already committed to, and shows where every GPU hour goes, so your team uses what it has before buying more.

Reserved GPUs this monthIllustrative
  • Training jobsRunning
  • Inference endpointsServing
  • Usage by projectReported
  • Guaranteed capacityProtected

Separate pools each keep their own headroom.

Training, inference, and agents and evaluation each need room for their peaks. Give each its own reserved GPUs and every pool carries spare capacity it rarely uses, all of it billed under your commitment.

On one prioritized pool, the same work shares a single headroom, because peaks rarely happen at the same time.

Same work, less headroomIllustrative
Separate pools: 340 GPUs, 97 of them headroom
Training pool200 GPUs
Inference pool100 GPUs
Agents and evaluation pool40 GPUs
Shared pool: 278 GPUs for the same work, 62 fewer
One prioritized pool278 GPUs

More of your commitment turns into work.

  • One pool for every workload

    Training and inference run concurrently on the same reserved GPUs instead of in separate fleets.

  • Guaranteed capacity stays guaranteed

    Mark the GPUs production depends on as protected. Other workloads never use them.

  • Usage you can show

    Reports attribute every GPU hour to a project, team and user, ready for internal chargeback and renewal decisions.

  • Live utilization

    Real-time telemetry shows how busy each GPU is, so idle capacity is visible instead of guessed.

  • Fewer lost hours

    Failing GPU nodes are isolated and replaced automatically, so reserved hours aren’t lost to bad hardware.

  • Popular clouds or your own servers

    Works on reserved capacity across Nebius, Google Cloud, Azure, DigitalOcean, OCI, AWS and on-premises GPUs.

Not free compute. Less duplicated compute.

Power, storage, networking and operations still cost money. The gain comes from not duplicating committed capacity across workloads, and from seeing exactly how the capacity you pay for is used.

Before you renew or expandWhat you’ll know
  • GPU hours by projectSee what each team used
  • Idle capacityVisible in real time
  • HeadroomShared, not duplicated

How GPU reservations are billed, and where the hours go

Committed capacity lowers the hourly price. It also changes what an idle hour costs you.

By the C-Gen.AI engineering team

You pay for every hour

Reservations and committed-use contracts trade flexibility for a lower rate, and the commitment is billed whether the GPUs are busy or not. It’s use-it-or-lose-it: an hour nobody used doesn’t roll over to next month.

Where reserved hours get lost

The usual suspects are capacity sized for one workload’s peak, GPUs waiting between experiments, nodes out of service with a hardware fault, and separate pools for training and inference that each keep their own spare capacity. Most of these losses stay invisible until someone measures them.

Measure before you renew

Before renewing or expanding a commitment, gather three numbers: average and peak utilization for each pool, GPU hours by team or project, and hours lost to faulty hardware. They turn “we need more GPUs” into a question you can answer: more GPUs, or more use of the ones you have?

Read the terms before you commit

Check which GPU types and regions the commitment covers, whether it can be exchanged or resized, and what happens when the term ends. Those details decide how much room you have later, when your models, your traffic or the GPUs on the market change.
Led by a world-class team

We’ve designed, built and run some of the largest AI training and inference systems in production.

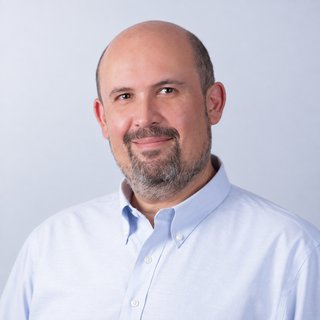
Dr. Sami Kama

Dr. Sami Kama

Founder & CEO
  • 17 years at CERN
  • Inventor, TensorFlow-TensorRT Integration (NVIDIA)
  • Inventor and Architect, AWS SageMaker
  • Inventor and Architect, AWS SageMaker HyperPod
  • Creator, SageMaker Profiler (world’s first distributed AI profiler)
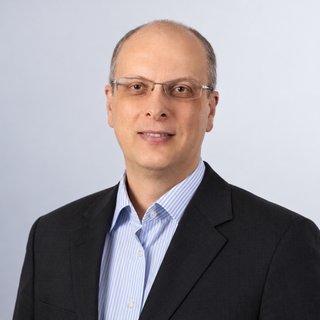
Richard Vencu

Richard Vencu

Head of Engineering
  • Former Head of HPC & MLOps, Stability AI
  • Managed one of the world’s largest AI training clusters
  • Co-Founder & Engineering Lead, LAION

Reserved capacity with Nucleaton™

Does it work with our existing reservation?
Yes. Nucleaton™ runs on the GPUs you already have reserved, in your own cloud account or data center.
Will production inference be affected?
No. Capacity you mark as guaranteed is never used by other workloads.
How do we measure the result?
Usage reports and real-time telemetry show how each GPU hour was used, by project, team and user.
How long does it take to start?
A new cluster typically deploys in about 25 minutes. Existing Slurm clusters join through an assisted deployment.

Get more from your reserved GPUs

Tell us about your reservation and workloads. We’ll show you how a shared pool would run on it.

The pool sizes shown are an illustrative example, not a guarantee of savings for your workload.

Our engineers usually reply within 4 business hours. See our Privacy Policy.