
Sovereign AI on B300: Kimi K3 and GLM 5.3 Speed and Cost Benchmarks vs Inference Provider APIs
- AI Infrastructure
- AI Deployment
By C-Gen.AI
In October 2026, we ran Kimi K3 and GLM 5.3 on a single NVIDIA B300 node with Nucleaton™. We measured output speed across multiple concurrency levels and compared the results with providers listed by Artificial Analysis. We then calculated how many tokens per month it takes for owning the node to cost less than paying for inference through an API.
How we benchmarked
- Hardware: one B300 node, on a spot instance.
- Workload: 10k input tokens and up to 10k output tokens per request, at concurrency levels from 1 to 64 simultaneous requests (C1 to C64).
- Metric: P50 output speed per request, retokenized with o200k_base so it is comparable across models and providers.
- Comparison: current 10k-input P50 figures for each provider from Artificial Analysis. AA does not publish its exact benchmark implementation, so we matched its disclosed methodology as closely as possible.
Kimi K3 speed on B300
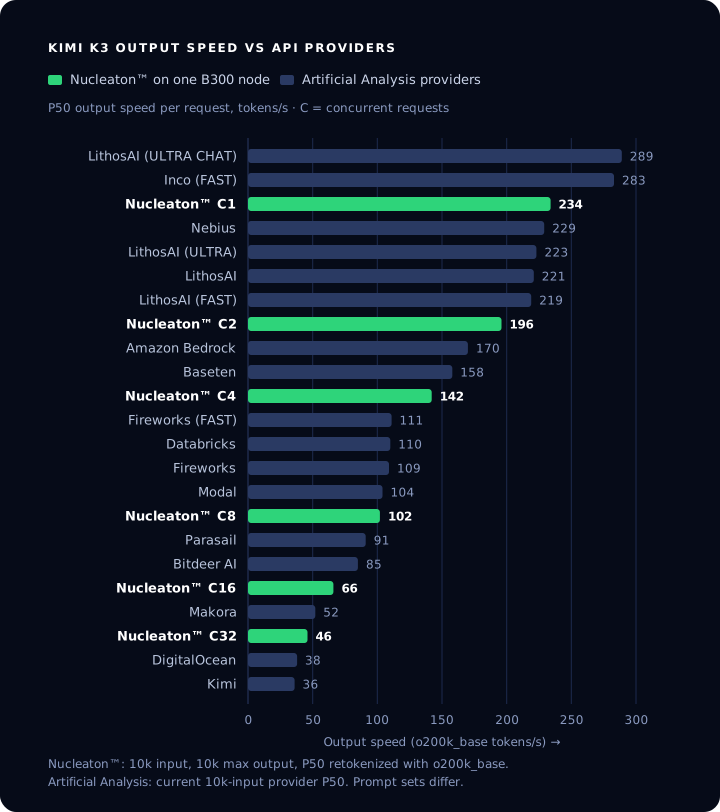
At one request at a time, Nucleaton reached 234 tokens/s, third of 23 entries and ahead of Nebius, Amazon Bedrock and Baseten.
How fast is GLM 5.3 on a B300 node?
At C1 Nucleaton reached 295 tokens/s, sixth of 33 entries, and it stayed above 100 tokens/s per request even at 64 concurrent requests.
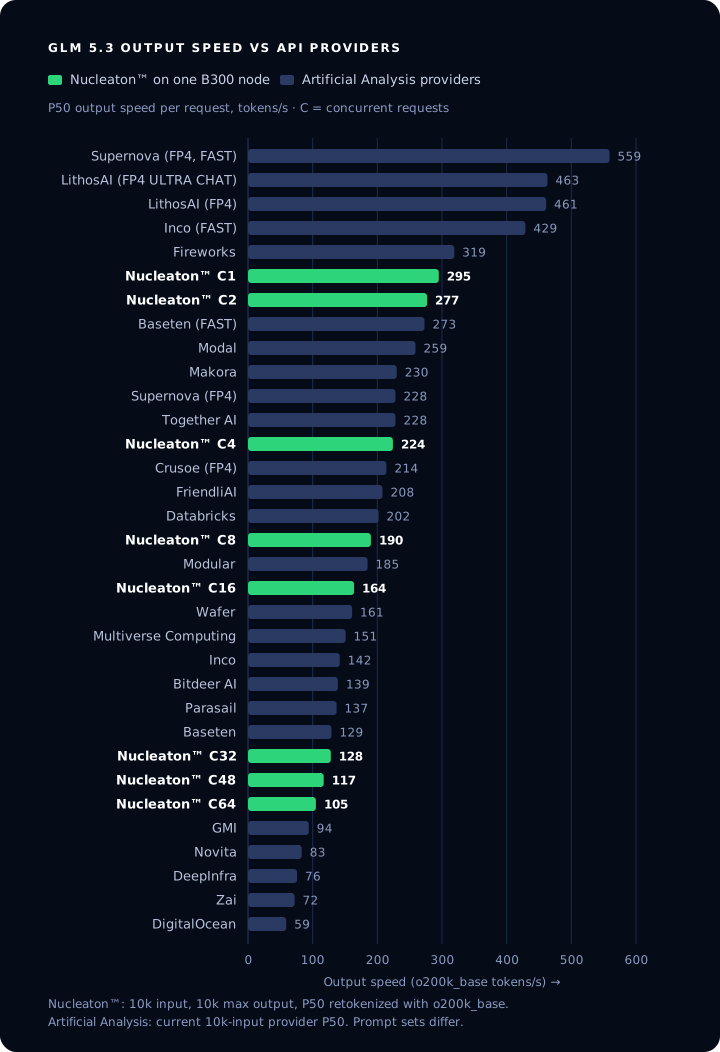
Nucleaton remained competitive with dedicated inference providers while giving the operator control over latency, throughput and cost, inside their own private infrastructure.
B300 vs API pricing: where is break-even?
Owning inference becomes attractive once usage crosses model-specific break-even points. The same infrastructure can continuously improve your models using your own data.
The economics
Break-even depends on model pricing. API costs scale with usage, while a dedicated B300 node’s monthly cost stays fixed.
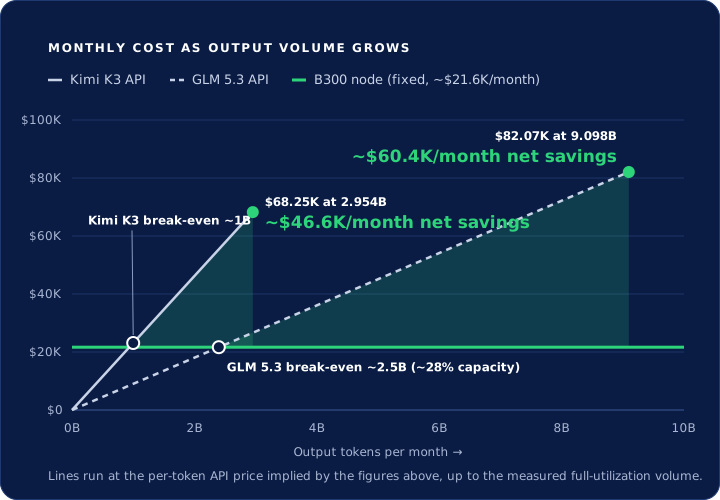
- Kimi K3, break-even: At ~1B output tokens/month, API cost is about $23.1K vs $21.6K managed node cost.
- Kimi K3, at full utilization: At 2.954B output tokens/month, API equivalent is $68.25K vs $21.64K managed node cost.
- GLM 5.3, break-even: At ~2.5B output tokens/month, API cost approximately matches the managed node cost.
- GLM 5.3, at full utilization: At 9.098B output tokens/month, API equivalent is $82.07K vs $21.64K managed node cost.
After break-even?
Sovereign AI that improves on your own data
When you buy API inference, your prompts and responses leave your infrastructure and the transaction ends with the response. When you run open models on your own infrastructure, the models, the traffic and the data stay under your control: the basis of sovereign AI. Inference traffic also becomes training data.
Nucleaton automatically collects traces from interactions with employees, agents and customers. When inference demand falls, idle GPU capacity can be used to post-train, specialize or distill models using those traces. When demand returns, the GPUs move back to inference. This is the same shared pool for training and inference that Nucleaton runs on every cluster.
- 1Run inferenceServe Kimi K3, GLM 5.3 or other models on your B300 infrastructure.
- 2Nucleaton™ collects tracesAutomatically capture real interactions, prompts, responses and metadata from inference traffic.
- 3Post-train / distillNucleaton automatically uses idle GPU capacity to post-train, distill or specialize models on your traces.
- 4Deploy improved modelsServe improved models on the same infrastructure with higher task accuracy and lower cost.
- 5Lower cost per useful tokenAs models improve on your data, serve more useful work at lower cost with higher accuracy.
FAQ
How much does a B300 node cost per month?
Assuming approximately $550K for a B300 node, a 36-month useful life, plus power, data center and Nucleaton costs, the managed node cost is approximately $21.6K/month. That cost stays fixed, while API cost scales with every token.
How many tokens a month justify owning a B300 node?
About 1B output tokens/month for Kimi K3 and about 2.4–2.5B for GLM 5.3, against a managed node cost of about $21.6K/month.
Is a self-hosted B300 as fast as inference API providers?
In our single-node test, yes for most of them: Nucleaton ranked 3rd of 23 for Kimi K3 and 6th of 33 for GLM 5.3 at concurrency 1.
Can you run sovereign AI on a B300 node?
The models, the inference traffic and the traces Nucleaton collects stay on infrastructure you control, and idle GPU capacity turns those traces into specialized models you own.
Raw benchmark data
Nucleaton™ output speed on one B300 node, by concurrency
| Concurrency | Kimi K3 (tokens/s) | GLM 5.3 (tokens/s) |
|---|---|---|
| C1 | 234 | 295 |
| C2 | 196 | 277 |
| C4 | 142 | 224 |
| C8 | 102 | 190 |
| C16 | 66 | 164 |
| C32 | 46 | 128 |
| C48 | not run | 117 |
| C64 | not run | 105 |
Monthly cost and break-even: one B300 node vs API pricing
| Kimi K3 | GLM 5.3 | |
|---|---|---|
| Managed B300 node cost | ~$21.6K/month | ~$21.6K/month |
| Break-even volume | ~1B output tokens/month | ~2.4–2.5B output tokens/month (26–28% of measured capacity) |
| Measured capacity | ~2.95B output tokens/month (C32) | ~9.1B output tokens/month (C48) |
| Equivalent API cost at measured capacity | ~$68.3K/month | ~$82.1K/month |
| Savings at measured capacity | ~$46.6K/month | ~$60.4K/month |
Kimi K3 output speed: Nucleaton™ vs Artificial Analysis providers
| Rank | Deployment | Output speed (tokens/s) |
|---|---|---|
| 1 | LithosAI (ULTRA CHAT) | 289 |
| 2 | Inco (FAST) | 283 |
| 3 | Nucleaton C1 | 234 |
| 4 | Nebius | 229 |
| 5 | LithosAI (ULTRA) | 223 |
| 6 | LithosAI | 221 |
| 7 | LithosAI (FAST) | 219 |
| 8 | Nucleaton C2 | 196 |
| 9 | Amazon Bedrock | 170 |
| 10 | Baseten | 158 |
| 11 | Nucleaton C4 | 142 |
| 12 | Fireworks (FAST) | 111 |
| 13 | Databricks | 110 |
| 14 | Fireworks | 109 |
| 15 | Modal | 104 |
| 16 | Nucleaton C8 | 102 |
| 17 | Parasail | 91 |
| 18 | Bitdeer AI | 85 |
| 19 | Nucleaton C16 | 66 |
| 20 | Makora | 52 |
| 21 | Nucleaton C32 | 46 |
| 22 | DigitalOcean | 38 |
| 23 | Kimi | 36 |
GLM 5.3 output speed: Nucleaton™ vs Artificial Analysis providers
| Rank | Deployment | Output speed (tokens/s) |
|---|---|---|
| 1 | Supernova (FP4, FAST) | 559 |
| 2 | LithosAI (FP4 ULTRA CHAT) | 463 |
| 3 | LithosAI (FP4) | 461 |
| 4 | Inco (FAST) | 429 |
| 5 | Fireworks | 319 |
| 6 | Nucleaton C1 | 295 |
| 7 | Nucleaton C2 | 277 |
| 8 | Baseten (FAST) | 273 |
| 9 | Modal | 259 |
| 10 | Makora | 230 |
| 11 | Supernova (FP4) | 228 |
| 12 | Together AI | 228 |
| 13 | Nucleaton C4 | 224 |
| 14 | Crusoe (FP4) | 214 |
| 15 | FriendliAI | 208 |
| 16 | Databricks | 202 |
| 17 | Nucleaton C8 | 190 |
| 18 | Modular | 185 |
| 19 | Nucleaton C16 | 164 |
| 20 | Wafer | 161 |
| 21 | Multiverse Computing | 151 |
| 22 | Inco | 142 |
| 23 | Bitdeer AI | 139 |
| 24 | Parasail | 137 |
| 25 | Baseten | 129 |
| 26 | Nucleaton C32 | 128 |
| 27 | Nucleaton C48 | 117 |
| 28 | Nucleaton C64 | 105 |
| 29 | GMI | 94 |
| 30 | Novita | 83 |
| 31 | DeepInfra | 76 |
| 32 | Zai | 72 |
| 33 | DigitalOcean | 59 |